Here’s a story that plays out in a lot of companies. A data team builds a model. It predicts well in testing, everyone claps in the demo, and then nothing happens. Six months later it’s still sitting in a notebook.
That’s not a modeling problem. It’s an engineering problem, and it’s the reason machine learning engineering exists as its own discipline. A prototype proves a prediction is possible. Production proves you can rely on it plug it into daily work and point to a business result.
The data is usually the first thing that breaks
Most teams can’t wait to get to modeling. Resist the urge to do that. Ask first, is our data actually support this?
In the real world information is almost never in one cohesive place. Some of it lives in the ERP some in the CRM, a large chunk is in excel files or other spreadsheet formats, and some pieces of information are buried deep in ancient and out-of-date documents. Before you create any model, you need to assess the integrity of the data who manages its who can update it, and if it is even consistent across multiple platforms.
You will also need reliable and consistent data streams in order to build pipelines to feed your model. A quick data assessment will be helpful to determine what inputs you can actually use, and it will save you from the costly revelation three months down the line of finding out half your inputs are useless.
Choose the model after you choose the decision
People love arguing which algorithm is best. They’re asking the wrong question. The correct question is, what decision do you want to improve? Then work backwards.
For example if you’re trying to determine how much product to produce and want to make an informed decision about the future, you ill want to take a look at forecasting. If you are trying to determine how to prioritize your case review and want to focus on only the most critical cases, you’ll want to look at scoring and ranking. If you want to determine something that seems “weird” or different, you’ll want to evaluate anomaly detection. The fanciest algorithm doesn’t always win. It’s about what is the fastest, what is the most accurate what is affordable what can your team maintain, and what explains your decision?
The easiest thing to use is the best thing to use, and you should use it. Custom algorithms are only warranted if you have a process so distinct and different, that your competitors have not articulated, that includes a huge amount of proprietary data. Beware of burning your budget on R&D and custom software.
An unused model is just an expensive file.
Pretend you’re a planner who has to manually input numbers in a different system, wait for a prediction, and input the answer in yet another system. How long before you stop entering the numbers? Not long.
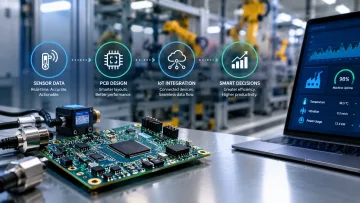
That’s why integration is key. Predictions must appear where users already work. This can be done through APIs, batch processes or real-time processes. Integrating it this way, means it becomes part of the system rather than an afterthought.
Using it the right way
Most companies use a mix of the big three cloud providers and, in most cases, the choice is dictated by existing infrastructure. Servers are the easy part. More challenging is who gets access, how do you create a separate environment for testing, how do you manage different versions, how do you get users to approve updates, how do you manage a release and how do you manage what gets deployed? A process that ensures you control what gets released and how it gets released, saves you from a lot of pain.
Models get worse quietly
Here’s where most folks get caught off guard. Customers act differently, prices shift, teams overhaul their processes—but the model just hums along, blissfully unaware. No warnings, no flashing lights. It just gets a bit less accurate each week, sneaking up on you.
That’s why MLOps matters. This is where you keep things in check: version control, deployment rules, drift alerts, retraining schedules, performance tracking—all of it. If you depend on a model to make daily decisions, you need to know it’s still pulling its weight today, not just remembering its good old days.
Watch the business numbers, not just the servers
Sure, watch the servers. Keep an eye on uptime, response times, system errors, and data quality. Those are basics. But they can’t tell you if your model actually makes a difference.
So judge the model by business outcomes. If it forecasts, have the forecasts really gotten better? Is planning easier now? If it’s supposed to score and filter, does it reduce redundant manual work? When you put technical metrics next to real business results, it’s much easier to spot when something’s off—and whether it’s time to retrain or retire the model altogether.
Put the rules in early
Once a model starts affecting real decisions, people start digging into the details. They want to know: Who gave this the green light? What kind of data feeds into it? Can you walk me through why it made that call? And what’s the plan if things go sideways?
You need approvals, tight access controls, solid audit trails, bias checks, and clear records—that’s how you answer those hard questions without breaking a sweat. If you bolt these on after everything’s up and running, it’s way more painful than just weaving them in from day one.
Should you outsource it?
You need data engineers, modelers, cloud experts, and folks who know MLOps and governance to get all this right. Let’s be real—hiring all those people takes ages.
So, outsourcing makes sense, but only if you’re clear about what you need. Do not just hand it off and say, “Go develop something. Set specific goals Usually, things kick off with an AI readiness check then you dig into data prep, building, testing, deployment, and ongoing support. Make sure everyone’s on the same page about what success looks like who owns what, and how you’ll manage everything from the start. That way, you’ll actually know when it’s time to move forward.
What good looks like
When it works you see fewer manual decision cycles, because repetitive analysis becomes a validated repeatable process. Forecasts get more accurate because operational data is used consistently. And the model is no longer a demo. Its just part of how the business runs.