Sedai says conventional GPU utilisation metrics can significantly overstate how efficiently AI infrastructure is running, leaving enterprises with large amounts of expensive compute sitting idle or underused.
13 October 2026 — Enterprises investing heavily in AI infrastructure may be wasting a substantial share of their GPU budgets because common monitoring tools do not show how effectively the hardware is actually being used, according to new analysis from Sedai.
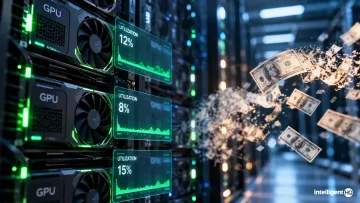
The cloud and AI infrastructure optimisation company says roughly one-third of GPUs operate below 15% utilisation, while even systems that appear heavily used can in practice be running at only 30% to 40% of their true capacity.
The issue matters because GPUs have become one of the most expensive components of enterprise AI infrastructure. Sedai says a single GPU instance can cost as much as 40 times more than conventional compute, meaning even modest inefficiencies can translate into substantial annual waste.
Traditional GPU metrics may hide the real problem
One of Sedai’s central findings is that organisations may be relying too heavily on native monitoring tools such as nvidia-smi.
The company argues that this metric can make a GPU appear heavily utilised even when the underlying compute resources are not being used efficiently.
According to Sedai, a GPU that reports more than 95% utilisation through standard metrics may still show a kernel efficiency of only 38%, indicating that much of its available capacity is not contributing to useful work.
Suresh Mathew, CEO and Founder of Sedai, says teams need to look deeper than whether a GPU is simply active.
The company’s analysis uses lower-level indicators including memory bandwidth, streaming multiprocessor occupancy and kernel efficiency to assess how much useful work a GPU is actually performing.
That difference between reported activity and real efficiency can make it difficult for infrastructure teams to know when they are over-provisioned.
One underused GPU can cost tens of thousands per year
Sedai estimates that a single GPU operating at around 30% utilisation can waste approximately $70,000 per year, based on current pricing for an NVIDIA H100.
The company says this is not an edge case but a pattern it sees in enterprise production environments.
As AI workloads scale across model training, inference, experimentation and internal applications, that level of underutilisation can multiply quickly across dozens or hundreds of GPUs.
For large enterprises, the result is not simply a technical inefficiency. It becomes a direct financial issue.
Unused capacity ties up budget that could otherwise support additional AI workloads, model experimentation or other infrastructure priorities.
Why GPU inefficiency is difficult to see
GPU environments are especially difficult to optimise because workloads can vary significantly over time.
Some jobs are bursty, some reserve more memory than they use, and others leave compute resources idle between processing stages. Infrastructure teams may therefore provision for peak demand even when average utilisation remains low.
Sedai argues that this creates a visibility problem.
If monitoring only shows whether the GPU is busy at a high level, teams may assume that utilisation is healthy even when substantial internal capacity is unused.
This becomes particularly important as AI workloads move from experimentation into production, where infrastructure costs are expected to be more predictable and accountable.
Autonomous optimisation could reduce waste
Sedai says autonomous optimisation can potentially reduce GPU spending by as much as 50% in some environments.
The approach works by analysing behaviour across multiple metrics rather than relying on a single utilisation indicator.
Systems can identify idle or underused GPUs, determine whether unused capacity can be shared and then adjust workloads accordingly.
One method is to run multiple compatible workloads on the same GPU when sufficient capacity remains available.
Rather than leaving unused compute stranded, the infrastructure can be consolidated dynamically.
Sedai positions this as a way to improve return on AI infrastructure without necessarily reducing the amount of AI work an organisation can perform.
AI infrastructure economics are becoming more important
The timing is significant because enterprise AI budgets are growing rapidly.
As companies deploy larger models, more inference services and more internal AI tools, GPU capacity is becoming one of the most closely watched infrastructure costs.
At the same time, management teams are increasingly asking whether AI projects are generating measurable business value.
That puts pressure on technology leaders to understand not only how much compute they own or rent, but how efficiently it is being used.
Sedai’s findings suggest that better utilisation could become one of the easiest ways for organisations to improve AI economics without changing models or abandoning projects.
Efficiency may become a competitive advantage
For companies scaling AI aggressively, infrastructure efficiency can influence how quickly they can experiment.
A team that recovers unused GPU capacity may be able to run more models, support additional internal applications or avoid new infrastructure purchases.
That can make optimisation a strategic issue rather than simply an operational one.
Sedai argues that organisations able to identify and right-size GPU usage faster will be better positioned to achieve positive returns from AI spending.
The company’s view is that the next stage of enterprise AI adoption will increasingly depend on how efficiently compute is managed, not simply how much hardware organisations can acquire.
The limits of headline utilisation numbers
The broader lesson from Sedai’s analysis is that GPU utilisation is more complex than a single percentage.
A machine can technically be “busy” without using its resources efficiently.
That means infrastructure teams need to distinguish between activity and productivity.
Metrics such as kernel efficiency, memory bandwidth and occupancy can provide a more complete picture of what is happening inside the GPU and whether the organisation is receiving full value from the hardware.
As GPU costs continue to represent a large share of AI infrastructure budgets, that distinction is likely to become increasingly important.
About Sedai
Sedai develops autonomous optimisation technology for cloud and AI infrastructure.
The company says its platform is used by organisations including HP, GSK and Palo Alto Networks to optimise infrastructure performance and costs.
Its GPU research focuses on identifying underutilised compute through behavioural and low-level performance signals rather than relying exclusively on standard utilisation metrics.